Tongyi-MAI/Z-Image
An Efficient Image Generation Foundation Model with Single-Stream Diffusion Transformer
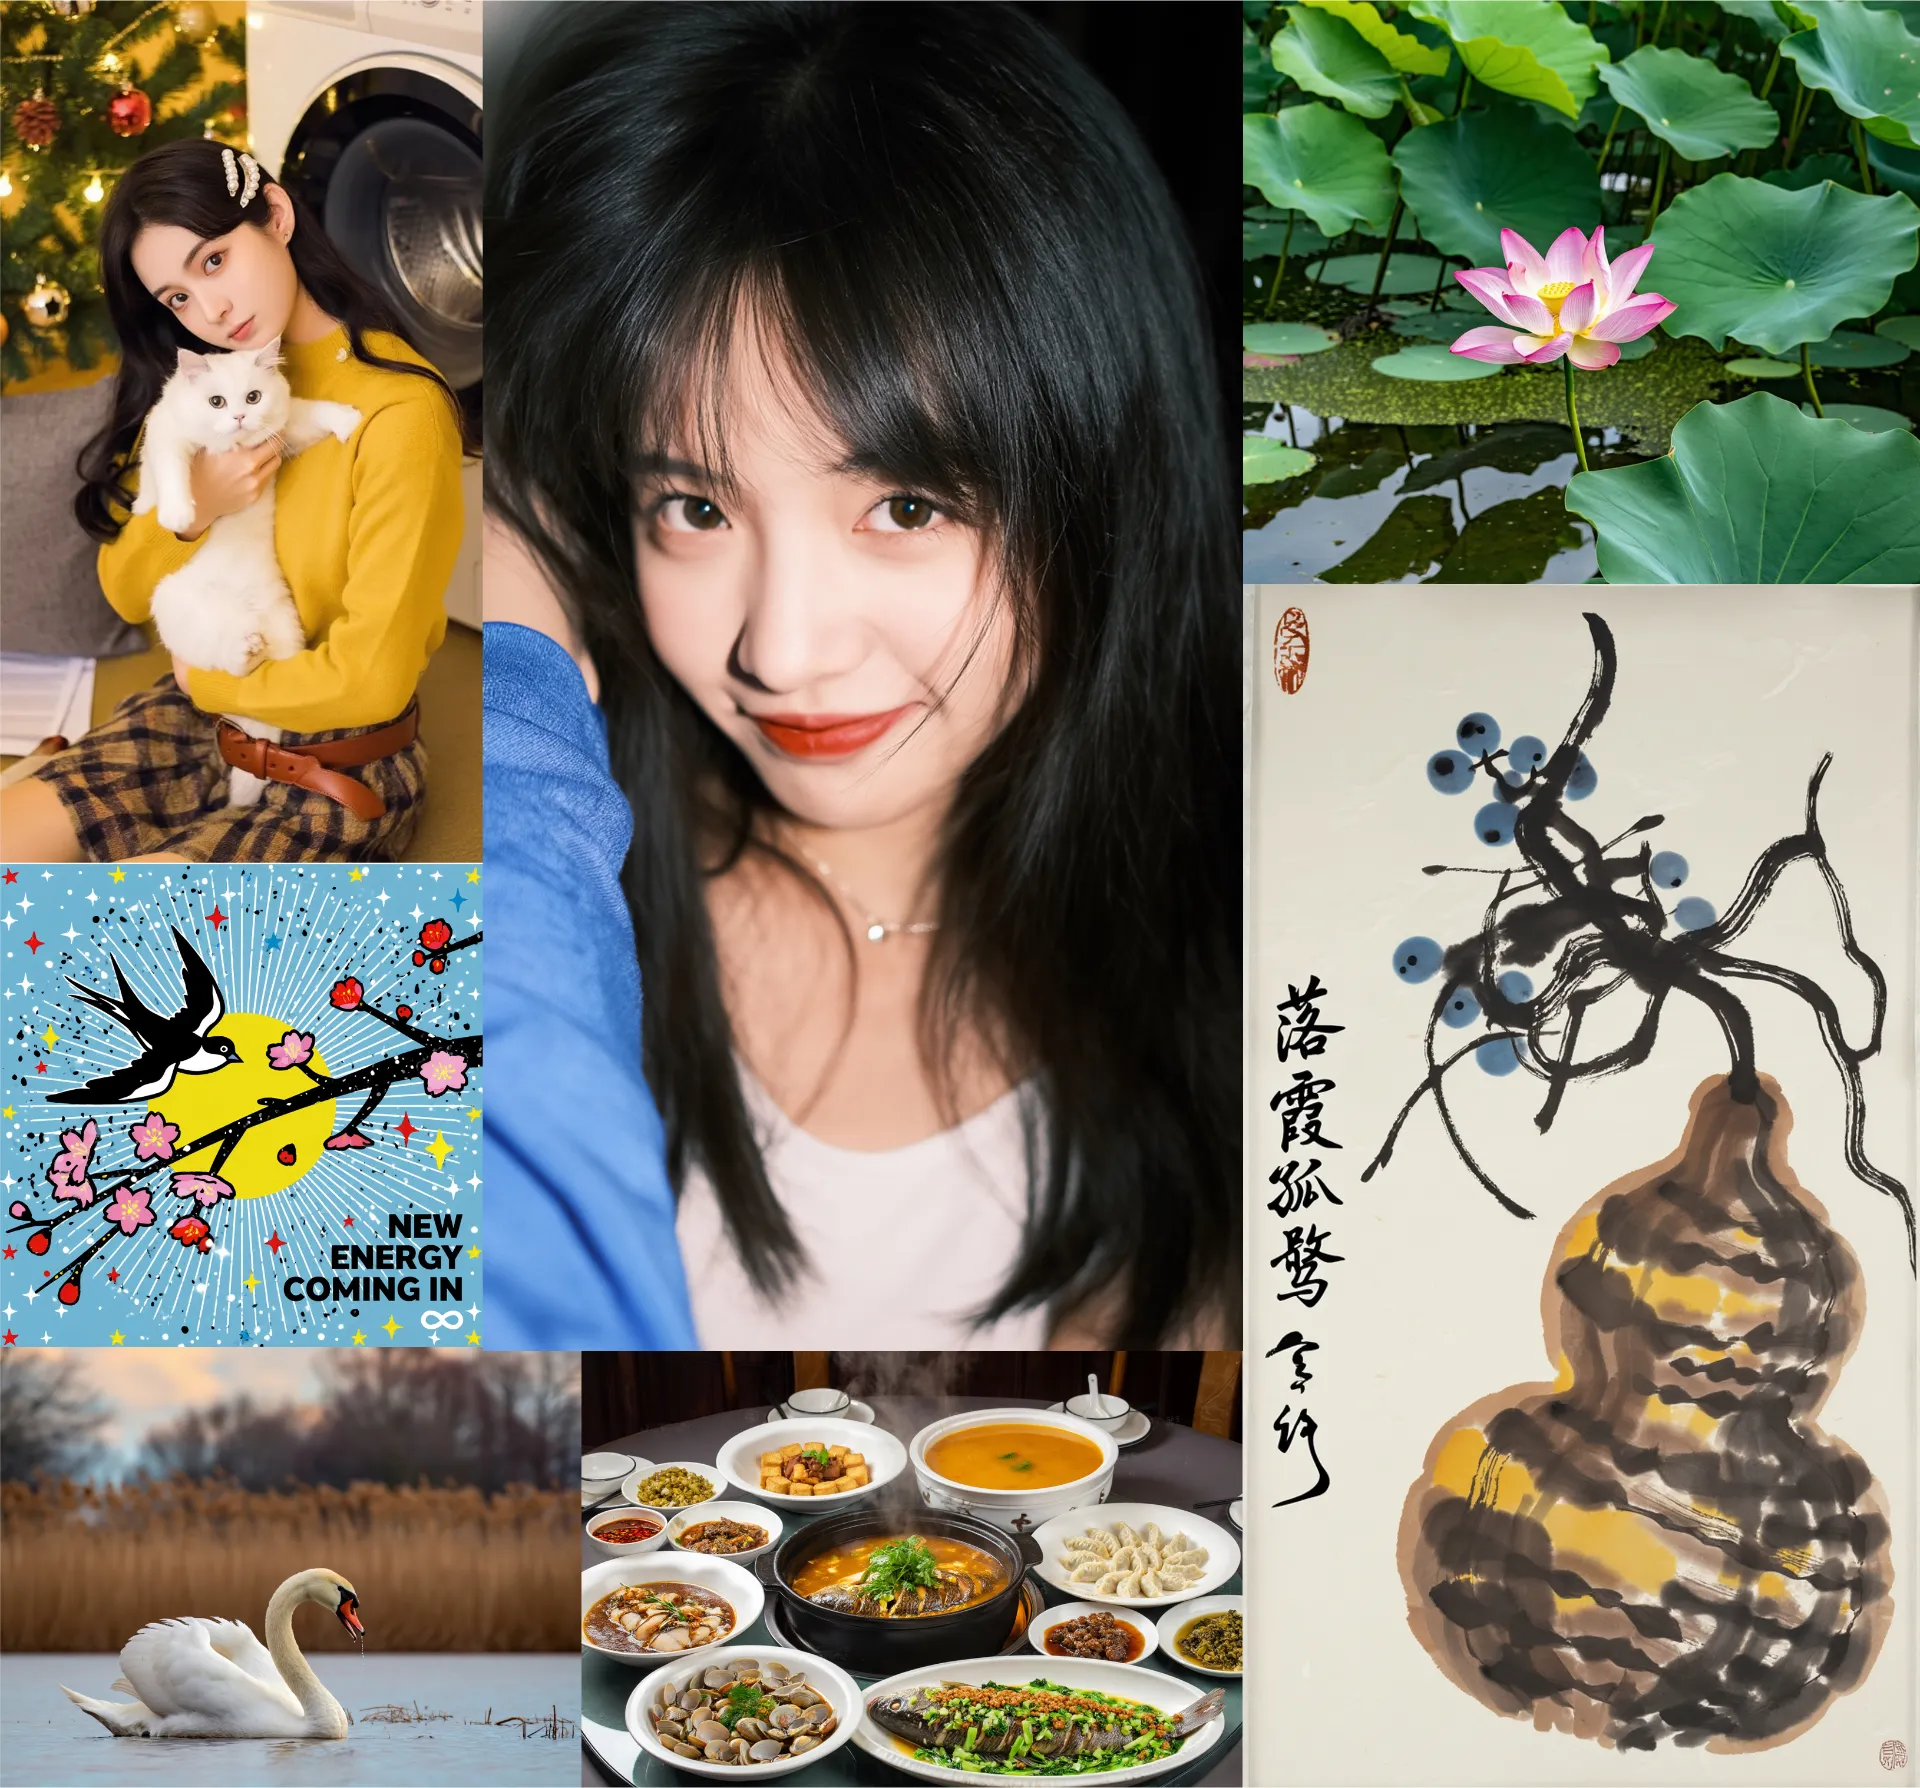
Z-Image is the foundation model of the ⚡️- Image family, engineered for good quality, robust generative diversity, broad stylistic coverage, and precise prompt adherence. While Z-Image-Turbo is built for speed, Z-Image is a full-capacity, undistilled transformer designed to be the backbone for creators, researchers, and developers who require the highest level of creative freedom.

🌟 Key Features
- Undistilled Foundation: As a non-distilled base model, Z-Image preserves the complete training signal. It supports full Classifier-Free Guidance (CFG), providing the precision required for complex prompt engineering and professional workflows.
- Aesthetic Versatility: Z-Image masters a vast spectrum of visual languages—from hyper-realistic photography and cinematic digital art to intricate anime and stylized illustrations. It is the ideal engine for scenarios requiring rich, multi-dimensional expression.
- Enhanced Output Diversity: Built for exploration, Z-Image delivers significantly higher variability in composition, facial identity, and lighting across different seeds, ensuring that multi-person scenes remain distinct and dynamic.
- Built for Development: The ideal starting point for the community. Its non-distilled nature makes it a good base for LoRA training, structural conditioning (ControlNet) and semantic conditioning.
- Robust Negative Control: Responds with high fidelity to negative prompting, allowing users to reliably suppress artifacts and adjust compositions.
🆚 Z-Image vs Z-Image-Turbo
| Aspect | Z-Image | Z-Image-Turbo |
|---|---|---|
| CFG | ✅ | ❌ |
| Steps | 28~50 | 8 |
| Fintunablity | ✅ | ❌ |
| Negative Prompting | ✅ | ❌ |
| Diversity | High | Low |
| Visual Quality | High | Very High |
| RL | ❌ | ✅ |
Similar to Tongyi-MAI/Z-Image
openai/gpt-image-1.5
OpenAI's latest image generation model with better instruction following and adherence to prompts
tencent/hunyuan-image-3
A powerful native multimodal model for image generation (PrunaAI squeezed)
stability-ai/stable-diffusion-3.5-large
A text-to-image model that generates high-resolution images with fine details. It supports various artistic styles and produces diverse outputs from the same prompt, thanks to Query-Key Normalization.
google/nano-banana
Google's latest image editing model in Gemini 2.5
prunaai/p-image
A sub 1 second text-to-image model built for production use cases.
recraft-ai/recraft-v3
Recraft V3 (code-named red_panda) is a text-to-image model with the ability to generate long texts, and images in a wide list of styles. As of today, it is SOTA in image generation, proven by the Text-to-Image Benchmark by Artificial Analysis